Skip to content

Research

One question runs through my work: what does it cost an AI system to learn and to decide, and can that cost be steered? Hydra made me treat computation itself as an optimization target; that led to asking when generation can be skipped altogether; Variance Collapse looks at the same question from the training side.

Deciding Without Generating

MLSys 2027 · Under review

An independent evaluation of typed, non-autoregressive decision models that output calibrated choices instead of generating tokens, tested on agent control, semantic cache guarding, and model routing. The result is one rule for when they pay off: only when the decision replaces downstream generation and cheap heuristics can't resolve the input.
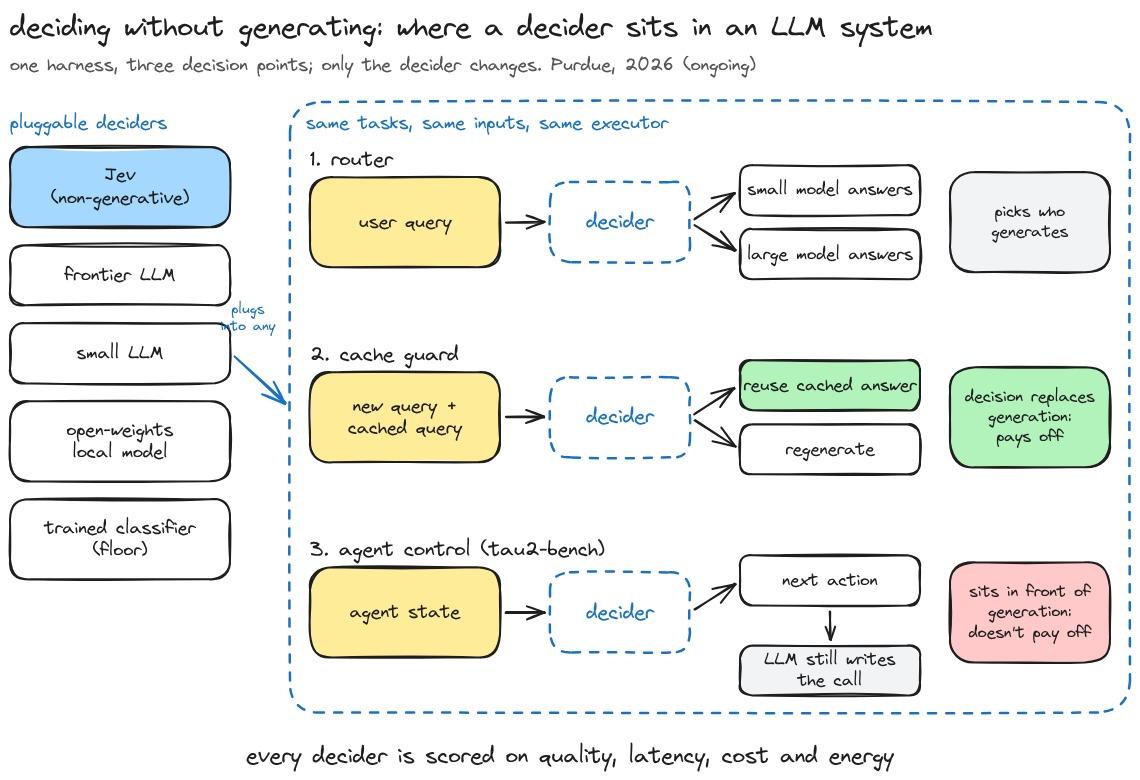
Pluggable deciders (Jev, frontier LLM, small LLM, open-weights local model, trained classifier) attached to three decision points on one harness: a router, a cache guard, and an agent controller.
One shared harness: the same pluggable deciders are evaluated at three decision points (routing, cache guarding, and agent control) on quality, cost, latency, and GPU energy.

My role: Project lead and first author, with co-author A. AlAzizy. Submitted to MLSys 2027 in October 2026; the linked PDF is the authors' preprint.

Abstract, method & results →

Abstract

Compound AI systems routinely call generative LLMs to make discrete decisions rather than to write text: which tool an agent calls next, whether a cached answer can be reused, which model should serve a query. Specialized "decision models" such as TypeSafe Jev, and open reproductions such as Kev, skip token generation and output a calibrated distribution over typed choices directly, and vendors claim orders-of-magnitude savings in latency and cost. This project tests those claims independently. It runs a consistent matrix of interchangeable deciders (Jev, Kev at 0.8B/4B/9B, GPT-5.6, GPT-OSS-20B, Qwen3-8B, trained classifiers, and non-neural baselines) on one shared harness across three decision points, measuring decision accuracy, end-to-end task completion, latency, dollar cost, and GPU energy.

Why it matters

Swapping an LLM call for a cheap decider sounds like a free win, but where the decider sits decides whether it saves anything. The study condenses this into a rule you can apply before building: add a standalone decider only where its decision can skip a generation, the input contains what the decision depends on, and the decision costs far less than the generation it may save. In agent control the generator has to run anyway to write the tool call, so a separate decider only adds cost. In cache guarding a correct decision skips generation entirely, and a decider at about 2% of the frontier model’s cost pays off. In routing, whether the cheap model will fail isn’t visible in the prompt, so a classifier trained on that model’s record wins.

Method

  • Agent control on τ²-bench airline: offline replay of 1,076 verified decision states (5 repeats each, 5,380 decisions per decider), plus in-loop runs of arms A–E across 50 tasks × 5 trials (1,250 episodes) to separate decision cost from execution.
  • Semantic cache guarding on three workloads: numerically perturbed reasoning (GSM-Plus), chat paraphrases (vCache LM-Arena), and real search queries (vCache SearchQueries), against cosine thresholds, cross-encoders, and vCache's per-prompt error bounds.
  • Model routing on RouterBench (0-shot) between Mixtral-8x7B and GPT-4, comparing general-purpose deciders with a lightweight classifier trained on target-model failure records.
  • Local deciders (Kev, Qwen3-8B via vLLM) served on dedicated A100-80GB GPUs via SLURM, with per-call energy read from the NVML cumulative energy counter and reported as both gross and idle-subtracted net joules per decision.
  • Two-stage cascades (similarity threshold → decider, and Jev → frontier LLM) with escalation thresholds picked by offline sweeps before the live runs.

Results

  • Cache guarding: on GSM-Plus, Jev reached 93.3% accuracy vs. 66.1% for similarity thresholds (+27.2 points, p < 0.05), vs. 81.7% for a classifier trained on that dataset, at about 2% of the frontier model’s cost per decision. A frontier LLM used as cache guard raised total cost to 138% of running without a cache.
  • Cascades: calling Jev only when similarity falls in an ambiguous band was best or tied for best on both chat and search traffic; on LMArena it called Jev on just 3% of queries, at $6×10⁻⁷ per query.
  • Agent control: a single frontier LLM choosing and executing in one call tied for the best reward (79.2%) at the lowest cost ($0.033 per success); every separate decider added cost or lost reward.
  • Routing: a small DistilRoBERTa classifier trained on the cheap model’s failure record recovered 64.9% of the small-to-large quality gap (APGR 0.649), beating every general decider, Jev included (+0.040 APGR).
  • Energy: on identical A100 hardware, Kev-9B matched Qwen3-8B's replay accuracy (40.1% vs. 39.6%) using about 20% less energy and running 17% faster, far from the order-of-magnitude gap seen in API prices.
  • Benchmark audit: the vCache datasets label reuse by query class rather than by pair, so the pairs were relabeled directly under a guideline fixed in advance, changing 6.0% of LMArena and 15.7% of SearchQueries labels; the corrected labels are released with the reason for each change.

Next steps

The paper is under review at MLSys 2027. Next steps are extending the evaluation to more agent domains beyond τ²-bench airline and testing whether decision models trained on target-model error surfaces can close the routing gap that general-purpose deciders leave open.
Hydra: Multi-Objective Code Optimization

DAC 2026 · Presented

A DPO-based framework that fine-tunes a code LLM to navigate sampled trade-offs across runtime, memory, CPU cycles, throughput, and energy instead of optimizing a single metric, by reading the model's own per-metric training signal each epoch and steering sampling toward whichever objective it's currently weakest on.

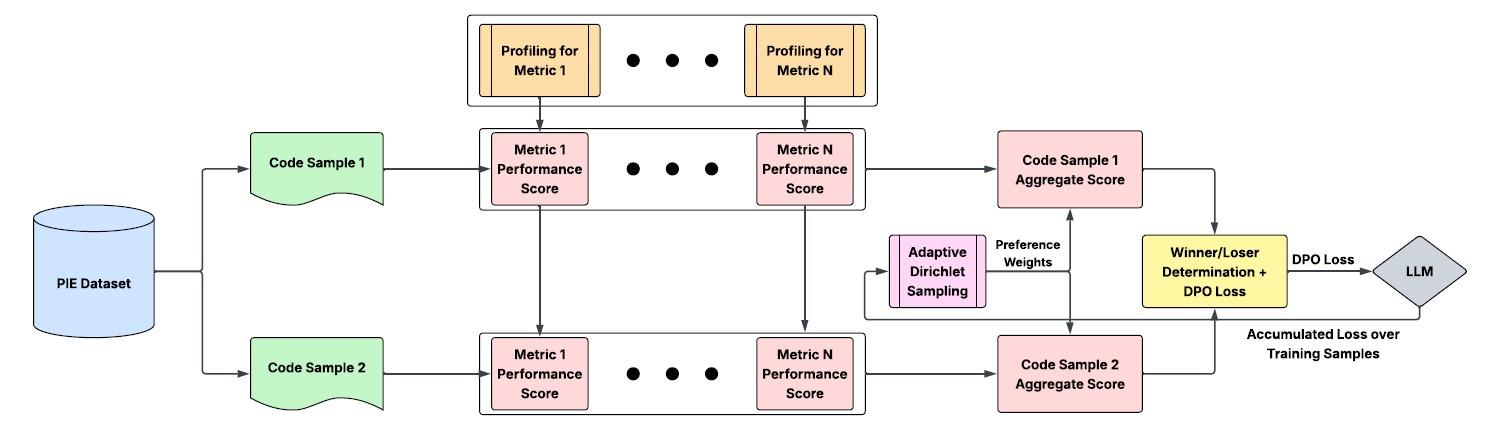
Hydra training pipeline: code samples are profiled across per-metric performance scores, aggregated via adaptive Dirichlet sampling into preference weights, and used to train the LLM with DPO.
Hydra pipeline: candidate implementations are profiled on five system metrics, weighted by an adaptively sampled preference vector, and turned into DPO preference pairs.

My role: Built by a 4-person Purdue VIP team (Arjun Gupte, Ahmed Elmersawy, Andre Lee, Stefan Maxim) advised by Prof. James Davis; presented as a poster at DAC 2026. My specific contribution: implementing and stabilizing the DPO training/inference pipeline; the QLoRA fine-tuning setup for Qwen2.5-Coder-7B-Instruct, including LoRA adapter integration and reference-policy handling; the adaptive Dirichlet multi-objective weighting mechanism for the Python model; the enriched 5-metric PIE data pipeline; and the inference-time evaluation benchmark and results in Table III. Baseline comparisons against GPT-5.4 and Efficoder, and the empirical study of prompt-based optimization, were led by teammate Arjun Gupte.

Abstract, method & results →

Abstract

Software optimization in practice is never about a single number. A rewrite that halves runtime but doubles memory use is not obviously an improvement the right trade-off depends on the workload, and that trade-off shifts from one deployment to the next. Existing automatic code optimizers either chase one metric at a time or require expensive, online RL training loops to learn trade-offs at all, so there was no offline, controllable way to teach a model to navigate runtime, memory, energy, and throughput together. Hydra closes that gap by framing multi-objective optimization as a preference-learning problem: given alternative implementations of the same task, the pipeline samples a per-example objective-weight vector from a Dirichlet distribution, profiles each candidate across five system-level metrics, aggregates them into a weighted reward, and uses the resulting winner/loser pairs to fine-tune a code LLM with Direct Preference Optimization (DPO), entirely offline, without generating or executing code during training. An adaptive sampling mechanism (Stage 5 of the pipeline) keeps the Dirichlet weighting from going stale: rather than fixing how often each objective is sampled, it classifies each sampled preference vector into a dominant-metric region, tracks the model's per-region DPO loss over an epoch, and updates the sampling concentration toward whichever metric the model is currently weakest on.

Why it matters

Our own baseline study found the failure mode this work fixes: prompting GPT-5.4 and an Efficoder fine-tune toward different objectives never produced a clean Pareto frontier across runtime, memory, and energy prompting alone doesn't reliably separate optimization objectives. Hydra's adaptive DPO training is a direct response to that result: it learns the trade-off explicitly and offline, instead of hoping a prompt can steer it, which makes the 'right' trade-off controllable at inference time rather than fixed by whatever objective happened to dominate training.

Method

  • Dataset built from the PIE optimized/unoptimized Python pairs: 36,857 raw entries, enriched and filtered to 35,752 usable preference pairs scored across latency, peak memory, CPU cycles, throughput, and estimated energy (cycles × 2.5×10⁻¹⁰ J).
  • Per-example preference weights sampled from a Dirichlet distribution over the five metrics; metric values normalized via sigmoid and aggregated into a weighted reward that labels each pair's winner and loser.
  • DPO fine-tuning of Qwen2.5-Coder-7B-Instruct with LoRA adapters under 4-bit NF4 QLoRA, warm-started from an earlier CodeQwen-1.5-7B-Chat checkpoint, run for up to 72,000 steps (lr 2×10⁻⁶, β=0.015) on a single A100 80GB GPU via SLURM, with checkpoint resumption across job slices.
  • Adaptive Dirichlet sampling: concentration parameters updated each epoch as αᵣ ← clip(αᵣ · exp(η(L̄ᵣ − L̄global)), αmin, αmax) raising the sampling weight on regions (runtime, memory, CPU, throughput, energy, balanced) where the model's loss is above average, lowering it where the model has already learned. In the full run, αmin=0.75, αmax=1.5, η=0.002.
  • The reweighting logic was validated standalone in a 100-epoch simulated training loop with hand-configured per-metric loss, isolating it from the rest of the DPO pipeline before relying on it in the full run.

Results

  • 46.7% average latency reduction, 36.0% CPU-cycle reduction, and 36.0% energy reduction across a 7-program held-out Python inference benchmark covering common inefficiency patterns (e.g. collapsing a triangular-sum loop to its closed form, nested-loop reduction, redundant sorting).
  • In a baseline study on HumanEval, GPT-5.4 outperformed an Efficoder fine-tune on every runtime/memory metric and prompting condition, but neither model produced a clean Pareto frontier across objectives from prompting alone evidence that prompt-based steering doesn't reliably separate optimization objectives, motivating Hydra's explicit tradeoff-aware DPO training.
  • Latency, CPU cycles, throughput, and energy ended up with consistently higher learned preference weight, while memory whose preference rate in the training data was only 39.4%, barely above chance was correctly down-weighted by the adaptive mechanism as an unreliable training signal.
  • DPO training loss stayed stable throughout the full run, indicating the adaptive multi-objective weighting did not destabilize preference optimization.

Next steps

explicit preference conditioning at inference time (steering the model toward a chosen trade-off via control tokens, without retraining), extending beyond the PIE Python benchmark to larger and more diverse codebases, and combining offline preference learning with limited online refinement as a hybrid approach. The current results are also explicitly preliminary: the correctness benchmark is small (7 hand-built programs), and the paper calls for evaluation on the larger PIE test split before drawing stronger generalization conclusions.

Variance Collapse & Gate Density

MMLS 2026 · Presented

Whether the fraction of gradient-carrying units rises or falls during training is treated as activation-specific folklore. This derives and empirically validates a mechanistic predictor from a single training-free quantity, across nearly 500 experiments spanning CNNs, MLP-Mixers, and Transformers, three datasets, and three optimizer families, the complement to Hydra: instead of steering training signal, this asks when it structurally disappears.

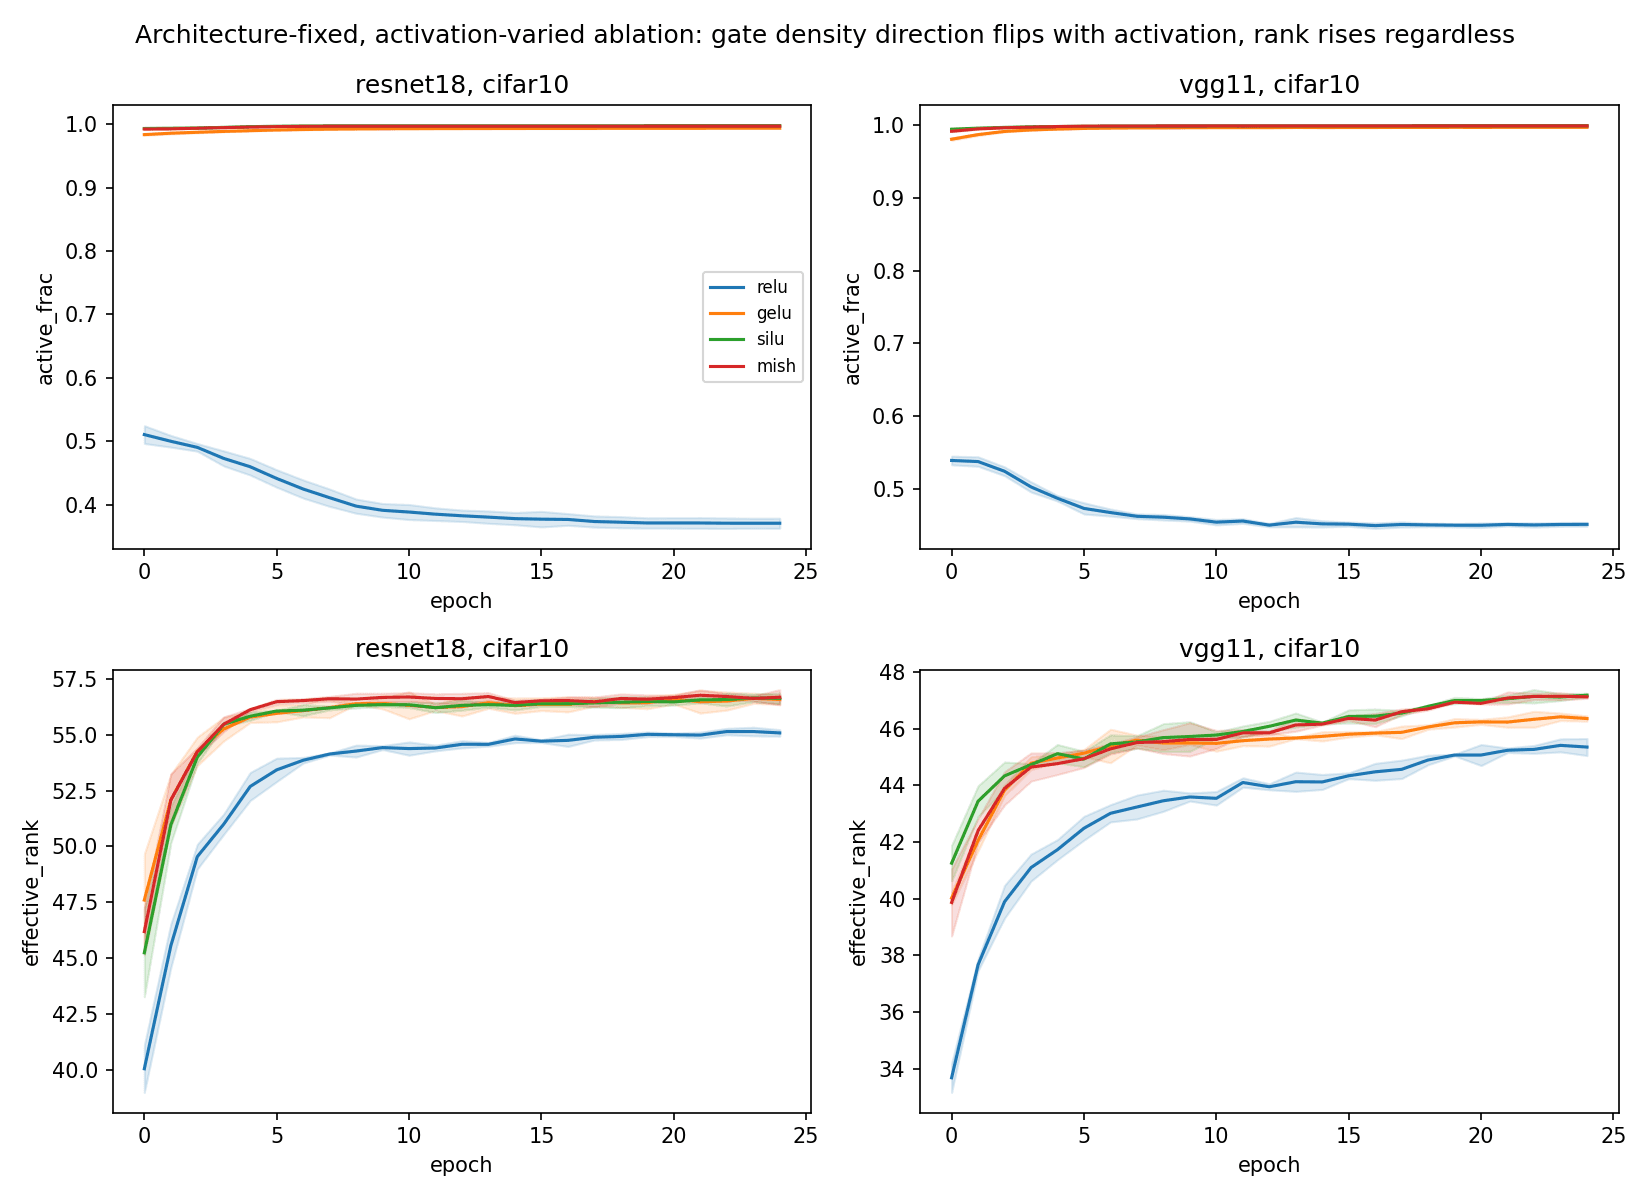
Architecture-fixed ablation on ResNet-18 and VGG-11 (CIFAR-10): the active fraction of ReLU units falls during training while GELU, SiLU, and Mish stay near one; effective rank rises for all activations.
Architecture-fixed ablation: gate density falls for ReLU but not for GELU, SiLU, or Mish, while representational rank rises regardless, so the direction is set by the activation class.

My role: Sole-author project. The theory and the full real-network study were presented as a poster at MMLS 2026.

Abstract, method & results →

Abstract

Whether a unit's local gradient |f'(x)| stays active or dies off during training its gate density is usually treated as activation-specific folklore: 'ReLU dies, GELU doesn't.' That folklore matters in practice (it drives intuitions about which activation to pick, when to worry about dead units, and whether gradient sparsity is safe to exploit for pruning), but it had no derivation, only anecdote. This work shows the direction gate density moves is not folklore but a derived consequence of a single, training-free quantity. Under coupled-weight-decay optimizers (SGD, Adam), the post-BatchNorm pre-activation variance collapses during training for every activation tested. Whether that collapse drives gate density toward 0 or 1 is predicted, across the tested activations, architectures, and optimizer regimes, by each activation's fixed threshold-crossing location, computable with no training via automatic differentiation. Under AdamW's decoupled weight decay, variance no longer collapses and the identical predictor, fed AdamW's own measured statistics with zero new free parameters, correctly anticipates a qualitatively different, uniform decline across every activation. The gate vocabulary and the threshold-crossing mechanism originate in an earlier, fully synthetic study working with a fixed single-layer convolutional reconstruction problem and a tunable sigmoid stiffness α, that study derives the same gradient gate Γ(x) = |h'(Ax)| and proves a phase transition between recoverable and unrecoverable gradient-based optimization. It carries over via an exact mathematical correspondence between Softplus's derivative and the logistic sigmoid, and is preserved as this paper's originating context.

Why it matters

Gate density is already used informally to reason about training health and as a candidate signal for pruning but without knowing whether its direction is mechanistically predictable, that reasoning is guesswork. Showing it's derivable from a training-free quantity means a practitioner can anticipate, before training even starts, whether a given activation/optimizer combination is likely to see rising or falling gate density, for the optimizer and architecture regimes this work studies, and the paper's three pre-registered negative results (gate density actively misleads channel pruning on smooth activations, doesn't discriminate via representational rank, and doesn't predict low-data fine-tuning accuracy) show that informal intuition was actively wrong, not just imprecise. More broadly, this is a small, concrete instance of a much larger open problem in deep learning: most claims about 'how training behaves' are empirical folklore rather than derived facts, and this work is a demonstration of what it looks like to replace one such piece of folklore with a derivable mechanism, validated across nearly 500 runs spanning three architecture families, three datasets, and three optimizer regimes.

Method

  • A hook-based instrumentation method (a backward hook reading the grad_input/grad_output ratio) recovers the exact pointwise gradient gate Γ(x) = |f'(x)| for any elementwise activation, without modifying the network or knowing f' in closed form.
  • An architecture-fixed ablation ResNet-18/VGG-11 skeletons held exactly identical, only the activation module swapped via constructor argument isolates activation effects from architecture confounds across ReLU, GELU, SiLU, and Mish (48 independent runs).
  • The mechanism connects BatchNorm's scale shrinkage under weight decay (an established result) to a fixed, activation-specific threshold-crossing point z_low(θ), verified at the population level, the per-channel level (a σ-normalized margin across 3,904 channels per run), and across a 13-condition continuous smoothness sweep (Softplus at multiple β values).
  • Generalization tested deliberately across optimizer (SGD/Adam/AdamW), scale (Tiny-ImageNet-200, a 365-class Places365 subsample), and architecture family (MLP-Mixer, Transformer-Encoder); every directional claim computed per independent seed trajectory and tested via an exact binomial sign test. Across the architecture-fixed ablation, generalization study, and synthetic analysis, the full study comprises approximately 500 runs.
  • Foundational synthetic study: a closed-form gradient gate derived for a fixed convolutional kernel and sigmoid activation, with a compounding-collapse theorem across depth, an oracle-rescaling ablation across five optimizers isolating Adam's momentum advantage from coordinate-wise rescaling, and an identifiability analysis via the effective Jacobian's null space.

Results

  • ReLU-based CNNs decline in gate density while GELU/SiLU/Mish rise instead; 12 of 12 ReLU runs decline and 12 of 12 smooth-activation runs rise in the architecture-fixed ablation (sign test p = 2.44×10⁻⁴ per activation).
  • Under AdamW's decoupled weight decay, all four activations decline instead of diverging by class (48 of 48 runs) and the same unmodified predictor, fed AdamW's measured per-channel statistics, anticipates this outcome with zero new free parameters (12 of 12 activation×seed cells correct).
  • The smooth-activation rise generalizes across the tested optimizer families (SGD, Adam, AdamW), scales (CIFAR, Tiny-ImageNet, Places365), and architecture families (CNNs, MLP-Mixer, Transformer-Encoder); the ReLU-specific decline and a separate effective-rank-rise observation both turn out to be CNN-specific.
  • In the originating synthetic study, reconstruction IoU follows a sigmoidal phase transition in stiffness α, with a separate identifiability (null-space) threshold at α* ≈ 11.7; an oracle ablation shows Adam's robustness in the high-stiffness regime comes from momentum's gradient-history accumulation, not coordinate-wise rescaling alone.
  • Three negative results are reported rather than omitted: gate density doesn't discriminate via representational rank, is actively misleading for channel pruning on smooth activations (65–80 accuracy points lost at 10% pruning vs. under 1.5 for magnitude pruning), and does not predict low-data fine-tuning accuracy (a pre-registered null).

Next steps

The paper is explicit about what it doesn't yet explain: it derives the direction of the effect, not its magnitude, and doesn't have a first-principles account of why AdamW's decoupled weight decay specifically prevents the variance collapse the mechanism depends on. ConvNeXt-Tiny is excluded from all claims as undertrained, and architecture families beyond CNNs, MLP-Mixer, and Transformer-Encoder along with full-scale ImageNet-1k remain untested. Closing those gaps, and testing whether the same threshold-crossing logic predicts gate dynamics in other architecture families, is the direct next step.